Spotify and Apple Music have a problem with AI-generated music. And the real musicians are paying for it
Music generated by AI has flooded the large platforms of streaming without anyone having asked for it. Deezer says it detects 75,000 AI tracks uploaded every day, and the number is growing. Spotify has uploaded 75 million songs of that type in the last twelve months. And Apple Music recognizes that more than a third of everything that comes to it is “100% AI”. Why is it important. It is not only a quality problem for the catalog or the reputation of the platform, but also an economic problem. Spotify, Apple Music and most platforms operate with a proportional distribution model (pro-rata): each artist receives a percentage of the total pool royalties equivalent to your reproduction quota. The more AI songs that accumulate listeners (even if they are fraudulent, generated by bots) the more it dilutes what a real musician earns. Between the lines. Although more and more music of this type is uploaded, almost no one listens to it, at least on purpose (sometimes AI songs sneak into algorithmic discovery lists). The problem is not the demand, which does not exist, but the brutal and increasing amount that distorts the algorithms and erodes the income of real artists even though their songs are still the ones that people do want to hear. Someone is uploading music that no one asks for to collect money that they do not deserve because the listeners arrive via bots. And that is money that the real artist stops earning. The background. The most extreme case, at least documented so far, has been that of Michael Smith, an American businessman who between 2017 and 2024 generated more than 10 million dollars in royalties wearing Suno and other tools to create hundreds of thousands of songs and armies of bots to play them automatically. That was the first case of fraud streaming with AI criminally prosecuted in the United States. According to the accusation, it accumulated 660,000 views a day. One billion views and zero fans. Yes, but. The platforms are already facing this wave. Deezer has been the most aggressive: it has implemented AI automatic detection, excludes those songs from algorithmic recommendations and has demonetized 85% of its views. Bandcamp has outright banned AI-generated music. Apple Music has begun to roll out its ‘Transparency Tags‘ (optional for now), and Spotify has released a verification stamp ‘Verified by Spotify‘ to ensure there is a human behind every artist profile. The problem is that both Spotify and Apple have opted for voluntary systems: it is the labels and distributors who must declare whether they have used AI. Nobody who lives off fraud is going to do it. There is an important distinction: It is one thing for a musician to use AI as a tool within their creative process (to refine a lyric, generate a base, experiment with sounds…) and quite another for an entire song to come out of Suno or equivalent with a pair of prompts and without real human intervention. The platforms, at the moment, do not distinguish between one thing and another. And Spotify has also left a door open by noting that “the concept of artistic authenticity is complex and rapidly evolving,” which in practice means that AI artists could end up being verified one day. Featured image | Xataka In Xataka | Science has measured how music impacts us during exercise: choosing the right Spotify list is essential
Fed up with paying almost 8 euros for a Guinness, someone thought of setting up an index to find cheap beer

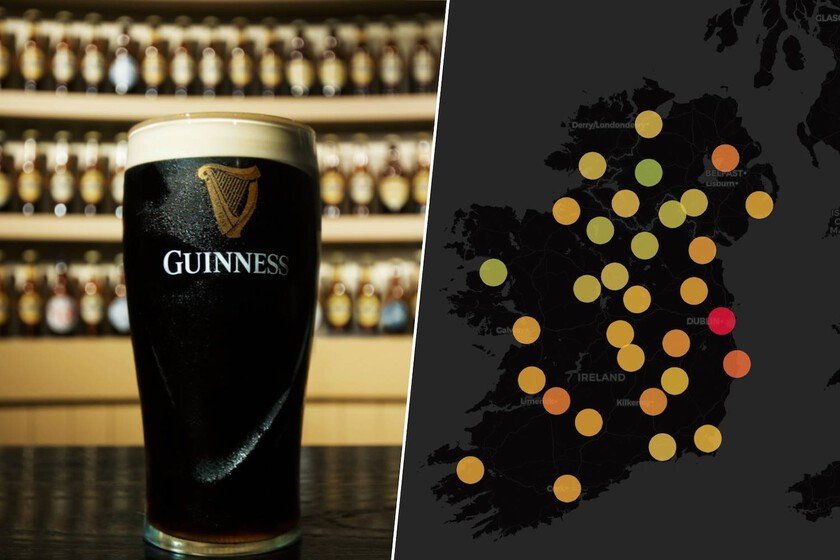
How delicious is that little beer that you drink right after leaving work or after a paddle tennis game and how angry it is when you find out that they have raised the price. Matt Cortland He paid €7.80 for a pint of Guinness in Dublin in March 2026 and didn’t like it one bit (the price, not the beer). So instead of criticizing the waiter or posting a review on Google complaining like some people do, he adopted another strategy that was slightly more laborious but much more effective (judging by its results): a very complete price index where he would know where to drink the best and at what price. Because revenge, like beer, is served cold. The project. Is called Guinndex and is independent of the very famous Irish beer brand. You go to the website, enter a pub, a city, a county or a postcode in the box and it returns pubs and the cost of a pint, as well as useful information such as its location or its score. Or you zoom in on the map to see with a traffic light map which taverns look cheaper than others. A good way to save if you travel to Ireland and fancy a pint of Guinness. In fact, it has very diverse rankings ranging from how long it takes to earn a pint (depending on salary) to pubs named after animals or the best pub names (praise be the “Hairy Lemon”). Today it has almost 6,500 registered pubs in the 32 counties of the country and almost 1,300 prices verified and rising thanks to anonymous contributions from users. The price index for Dublin. Guinndex Why is it important. Because the Irish Central Statistics Office stopped tracking the price of a pint since 2011, leaving a data gap of more than a decade in a country where Guinness is much more than a beer. And although Guinness is almost a religion in Ireland, it is the same everywhere: no one knows for sure if they are overcharging you compared to the standard price or how much extra. The Guinndex fills that gap with real, verified data, not estimates. Furthermore, it does so publicly and for free, so that it allows obtaining an objective reference so that consumers have information and can put pressure on prices. It’s the market, friend. On the other hand, and leaving aside the anecdote of finding where to drink cheaper, what it shows is relevant: that the cost of carrying out a complex idea has plummeted and streamlined so much that a single dev is capable of setting up a project of this magnitude in just 48 hours when before it took weeks of work, a certain budget and a team. Context. Matt Cortland likes AI, data and Guinness, as he himself admits on the project website. He is an American engineer based in London with strong ties to Ireland: his partner is irishlived and trained there with the George Mitchell scholarship and course the Creative Digital Media master’s degree from TU Dublin. He is not just a tourist they are trying to scam. The project came at a critical time: Diageo, the company that owns Guinness, had applied several price rises in a row and some pubs had taken the opportunity to inflate margins. If you’re not careful, you can pay up to €11 for a pint, although the average price in Dublin is €6.94 and €6.06 nationwide. How has he done it. With an AI agent named Rachel who looked human, understood Irish humor, and had a Northern Irish accent (after several tests, she concluded that this worked best), as its author tells. The task was simple and quick: call, ask the price of a pint of Guinness, say thank you and hang up. Few people discovered that it was a chatbot and there were all kinds of responses, even waiters who offered to buy him a round. During the St. Patrick’s weekend he called 3,000 pubs, answered more than 2,000 calls and more than a thousand pubs provided a price: he already had the Guinndex base. The technical stack was jack, knight and king: the Google Maps API, ElevenLabs for the voice and agent logic, Twilio for making the phone calls, and Claude for extracting Guinness prices from the transcripts. Cortland explains What cost him the most was time, since he only invested about 200 euros. The consequences. The most immediate impact is behavioral: Cortland account that the owner of a pub lowered the price of his Guinness by 0.40 euros and then updated the information in the Guinndex himself. When there is price transparency and it is available to everyone, it is capable of changing behaviors. However, the biggest consequence is the technological moment in which we live: three APIs, 200 euros and a weekend are enough to build a project from scratch, with real utility and that is already changing prices. The bottleneck is no longer money or infrastructure: it is knowing what problem is worth solving. In Xataka | Spain can tell itself as many times as it wants that it hates Cruzcampo. The figures say a very different thing In Xataka | We humans like beer. The big question is whether we like it enough to have invented agriculture Cover | Guinndex and Christopher Zapf

The world will run out of memory for AI chips until 2027. And cell phones and cars are already paying the price

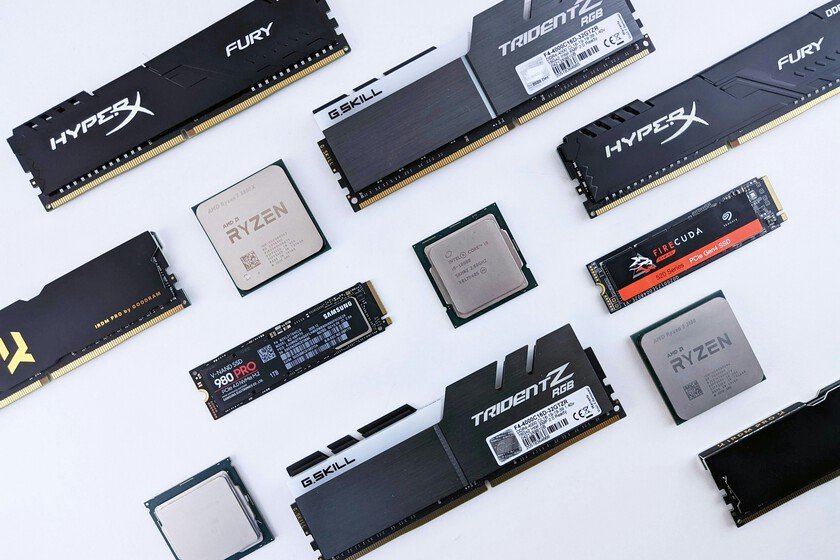
The big bottleneck in the artificial intelligence industry has nothing to do with AI models, GPUs, or data centers. It has to do with memory, and for months we are immersed in a crisis of which now the manufacturers give us more information. Three companies—Samsung, SK Hynix and Micron—control 90% of global production, but current estimates indicate that between the three They can only cover about 60% of expected demand through 2027. That’s terrible news not only for AI, but also for everything non-AI. The era of memory scarcity. These three manufacturers have prioritized HBM production for AI accelerators because these memories leave better margins. The direct consequence is the shortage of DRAM memories, which are used in PCs and mobile phones, and since October 2025 we have seen how this market has skyrocketed in price. Betting everything on one segment has left the other dangerously neglected. Samsung will have new factories. According to indicate In Nikkei, Samsung plans to launch its fourth memory manufacturing plant in Pyeongtaek, South Korea, in 2026, although mass production will not begin until 2027 or later. Furthermore, not only memories will be manufactured in that plant. There is a fifth plant under construction on that same technology campus, but it will be dedicated to HBM chips and will not begin operating until at least 2028. The South Korean giant has another ace up its sleeve: the United States. HBM to power. SK Hynix is ​​the only one of the three that has a concrete supply improvement for 2026, because it has already started manufacturing HBM chips at its Cheongju plant in February. It is also accelerating construction of a plant in Yongin, near Seoul, with the goal of completing it by February 2027. Micron also asks for patience. Meanwhile, Micron, the American company, has the goal of starting production of HBM chips in Idaho and Singapore in 2027, and will build a factory in Hiroshima that will theoretically come into operation in 2028. It has also just purchased a plant in Taiwan from Powechip, but the chips that come out of it will not be available before the second half of 2027. This is not enough. The consulting firm Counterpoint Reserach estimates that in order to resolve the current DRAM crisis, an industry-wide production increase of 12% annually until 2027 would be required. However, current plans add up to a growth of 7.5%, which makes it clear that these expansions by these three manufacturers are not enough. For Counterpoint analysts, the consequence is clear: the balance between supply and demand will not be normalized until 2028. SK Hynix is ​​already talking about supply limitations for AI chips could last until 2030, and the truth is that all the forecasts only confirm that this problem will still last for years. We consumers pay the price. Memory is an absolutely transversal product that is everywhere. 80-90% of current memory chips go to computers, mobile phones and servers, and the rest to cars and industrial equipment. The most direct impact is already in the mobile market entry-level: memory already represented 20% of the manufacturing bill for one of these smartphones, but that figure is expected to reach 40% by mid-2026. That gives manufacturers few (or no) options, which will impact that cost on the price of these devices. And so with everything. IDC esteem that mobile sales will fall by 13% in 2026 due to this circumstance. The danger of cycles. The memory industry has a history of cycles in which the rise and fall of memory prices is traditional. In 2023 there was a collapse in prices after post-pandemic demand for PCs faded. Several manufacturers recorded historic losses, and learned the lesson of overproducing to meet demand. Now that we need more production, manufacturers are being much more cautious when it comes to increasing their production or investing in new factories. For them, by the way, the crisis is going great: Samsung has earned in three months of 2026 what it earned in all of 2025. China to the rescue. Although South Korea and the United States dominate global memory production, there are several Chinese manufacturers that are gradually gaining relevance. YMTC and CXMT They have been growing significantly in production for some time and that is making now have a golden opportunity to gain market share over competitors that they seemed unattainable. Image | Liam Briese In Xataka | The situation with RAM prices is so desperate that there are already those who build their own memory at home

They have kidnapped agents from Anthropic, Google and Microsoft for the sake of science. The three companies ended up paying

In some development teams it is already becoming common to rely on artificial intelligence agents to review incidents, analyze code changes and move through tasks that were previously left in human hands. The problem appears when these systems not only read information that may come from outside, but also operate in spaces where they coexist. sensitive keys, tokens and permissions. That is what recent research puts on the table: we are not simply facing a useful tool that can make mistakes, but rather an architecture that can also become dangerous if it is deployed without very clear limits. The alarm has been turned on Aonan Guan and Johns Hopkins researchers Zhengyu Liu and Gavin Zhong after demonstrating attacks against three agents deployed on the aforementioned platform: Claude Code Security Review, from Anthropic, Gemini CLI Action, from Google, and GitHub Copilot Agent, a GitHub tool under Microsoft. According to your documentation, The failures were communicated in a coordinated manner and ended in financial rewards paid by the companies, but what is relevant is that they point to a broader problem. This is how they managed to twist the agents from within The name that Guan gives to the discovery helps a lot to understand what this is all about: “Comment and Control.” The idea is simple to explain, although the substance is not so simple. Instead of setting up an external infrastructure to direct the attack, GitHub itself acts as an entry and exit channel: the attacker leave the instruction in a titlean incident or a comment, the agent processes it as if it were part of normal work and the result ends up reappearing within that same environment. Everything stays at home, and that is precisely the key to the problem. And that “everything stays at home” is not a minor detail, but the basis of what the research describes. The three agents share a very similar logic: they read normal content from GitHub, incorporate it as a work context, and from there, execute actions within automated flows. The clash appears because that same space not only contains text sent by third parties, but also tools, permissions and secrets that the agent needs to operate. The first case Guan details concerns Claude Code Security Review, an Anthropic GitHub action designed to review code changes and look for possible security flaws. Up to this point, everything is within what was expected. The problem, as the researcher explains, is that it was enough to introduce malicious instructions in the title of a pull requestwhich is the request that someone sends to propose changes to a project, so that the agent will execute commands and return the result as if it were part of your review. The team then managed to go a step further and demonstrate that it could also extract credentials from the environment. The interesting thing is that the same scheme also appeared in the other two services, although with nuances. At Google, Gemini CLI Action could be pushed to reveal the GEMINI_API_KEY from instructions snuck into an issue and its comments; In GitHub Copilot Agent, the variant was even more worrying, because the attack was hidden in an HTML comment that a person did not see on the screen, but the agent did process when another person assigned it to the case. In both scenarios, the background was the same again: apparently normal content that ended up twisting the behavior of the system until exposing credentials or sensitive information within GitHub itself. Guan assures that the pattern made it possible to leak API keys, GitHub tokens and other secrets exposed in the environment where the agent ran, that is, just the credentials that can later open the door to much more delicate actions. Who does this affect? Especially to repositories that run agents in GitHub Actions on content sent by untrustworthy collaborators and, in addition, give them access to secrets or powerful tools. The researcher himself clarifies that the risk depends a lot on the configuration: by default GitHub does not expose secrets to pull requests from forksbut there are deployments that open that door. And here another layer of the matter appears, less technical but just as important. As published by The RegisterAnthropic, Google, and GitHub ended up paying bounties for the findings, but none of the three had published public notices or assigned CVE at the time of that information. Guan was quite clear about this: he said he knew “for certain” that some users were still stuck on vulnerable versions and warned that, without visible communication, many may never know that they were exposed or even being attacked. So although there were mitigations and changes in documentation or in the internal treatment of reports, there was no equivalent public notice for all those potentially affected. Anthropic settled the case on November 25, 2025 and paid $100 Google rewarded the discovery on January 20, 2026 with $1,337 GitHub closed the case on March 9, 2026 with a payment of $500 What makes this case especially delicate is that GitHub does not seem like the end of the road, but rather the first visible showcase. Guan argues that the same pattern can probably be reproduced in other agents who work with tools and secrets within automatic flows, and there he mentions from Slack-connected bots to Jira agentsmail or deployment automation. The logic is the same again: if the system has to read external content to do its job and also has enough access to act, the field is fertile for someone to try to twist it from within. The conclusion that Guan reaches is not about selling a magic solution, but about returning to a fairly classic idea in security: giving each system only what is essential to do its job. If an agent reviews code, they shouldn’t have access to tools or secrets they don’t need; If you’re just summarizing issues, it wouldn’t make sense for you to write to GitHub or touch sensitive credentials. That … Read more

You can live without paying Google for more storage. The problem is not space, but Gmail

I know firsthand that the offers that Google launches for your One plan cheaper are attractive. Paying a couple of euros a month so that the company does not bother you with warnings that you have little storage left is perfectly valid and you immediately get 100 GB so you can use it however you want. However, although it may not seem like a big deal, it ends up being a small “phantom expense” that we can easily avoid if we change our spending habits a little. cloud storage. In the vast majority of cases, the main culprit that causes us to have consumed almost all of the 15 GB that Google makes available to us for free is email. And the good thing is that they exist ways to almost immediately empty our inbox and have that free storage back. Below these lines we indicate some recommendations that will help you. 10 GOOGLE APPS THAT COULD HAVE SUCCESSFUL The problem is in your inbox If you check what takes up the most space in your Google account, it is quite likely that you will be surprised: Gmail is usually the biggest storage hog. Other times, it is also Google Photos that gives the most trouble with this, but in the case of Gmail, emails with attachments accumulate for years, and most of them are perfectly expendable: automatic notifications, old invoices, newsletters that you never read, etc. If your work depends to a certain extent on being very aware of the email, as happens to me, you find thousands of emails of press releases, presentations and, in short, material that arrives, takes up space and you don’t open it again. The good thing is that Google gives you very specific tools to locate those emails that we do not need and delete them in bulk. Between that and some tips to filter your inbox, you will be able to empty a very important part of the free storage that Google gives you in a simple way. The starting point: Google’s storage manager Before you get to work with Gmail, there’s one place worth going first: Google’s storage manager, accessible directly from this website. You can also get to it by clicking on the storage tab in Drive and clicking on “Free up space”, an option included in the Drive, Photos or Gmail app. This page shows how much space you have occupied and offers two key sections: one with personalized suggestions to free up space (such as deleting spam emails, large files or heavy attachments, indicating how much can be gained in each case) and another with shortcuts to the specific management of Drive, Gmail and Google Photos. It’s a good way to get a general idea of ​​the picture before acting: at a glance you can see which service is consuming the most and where to start cleaning. How to find and delete what matters most in Gmail If you’ve noticed that Gmail is taking up quite a bit of your cloud storage, the next step is to take action. After having deleted the emails that the Google One system itself suggested in the previous step, you can continue on your own using advanced filters that Gmail offers you, going for the heaviest emails first. To do this you can start by writing in the Gmail search engine ‘larger:15MB‘ (without the quotes) and so you will see all the emails that exceed that size. You can adjust the number depending on what you want to find: larger:5MB, larger:10MBor whatever value you prefer. It is a quick way to identify the messages that take up the most space with minimal effort. It is one thing to identify them, and quite another to know if they are really important to you or not. Going one by one is a bit of a hassle, but for example it helps me a lot to know if the email is from a long time ago or not. That’s why I also use date filters. This way, if what you want is to go also old, the command before:YYYY/MM/DD shows messages sent or received before a certain date. You can even combine both commands to locate old and heavy emails at the same time. Another very practical option is to search directly by attachments. Wearing has:attachment larger:10M All emails with attachments larger than 10 MB appear in the search bar. If you want to tune more, filename:.pdf larger:5M specifically locates emails with PDF attachments that weigh more than that amount, and older_than:2y has:attachment Filter out those that have attachments and have been in your tray for more than two years. Attached files (photos, PDFs, videos, documents) are usually responsible for the storage filling up much faster than expected. Search your keywords Beyond the commands that Gmail offers you, you can also use searches that serve you personally. In my case, for example, when I have a long list of press releases that I have already read, I simply type ‘ndp’ or ‘press release’ in the search engine and I will easily have a whole long list of press releases waiting to be deleted. Then you just need to pull the trigger. Once you have identified all the emails you want to delete, click on the selection square in the upper left corner to mark them all, click on ‘Select all conversations that match this search‘ so you can mark them all and not just the first 50, and then pull the trigger. If you know exactly what you DON’T want to delete, you can move it to its own label or mark it as featured before mass deleting the rest. That way you don’t risk losing anything important. Don’t forget to empty the trash When you have identified and deleted all the emails, you will have to pay a visit to the trash. And the emails that you have deleted do not disappear immediately: they are sent to the trash, where stay for 30 … Read more

Instagram wants you to be able to gossip about your ex’s stories without getting caught. Paying, of course

Instagram stories they turn ten years old soon and the company is preparing a novelty that could completely change this product. The format, popularized by Snapchat, has some basic “rules”, such as that they disappear after 24 hours and that we can know who has seen our story. Instagram suggests that we can bypass these and other rules if we pay a subscription. Instagram Plus. This is what this new subscription model will be called, as they say in TechCrunch. Meta is testing a paid subscription for Instagram that will allow users to enjoy a series of benefits over normal features. Currently, Instagram has the Meta Verified subscription option (to have the blue tick) aimed at creators, but this new subscription is aimed at normal users who want to have certain benefits. Meta’s goal with this move is to diversify Instagram’s sources of income, which mainly come from advertising. Functions for the stalking. In an email to TechCrunch, Meta has detailed what extra features will come with the subscription. It is striking that the majority of functions fuel, let’s say, unhealthy uses of the platform, just when Meta has been found guilty of having designed its products to generate addiction. The functions of Instagram Plus are as follows: View stories anonymously, without the person who posted them knowing. Know which people have viewed your story more than once. Search within the list of viewers, to find out if a specific person has seen your story without having to search the list Extend the length of stories for an additional 24 hours. Feature a story so it appears at the top of your followers’ stories carousel. Send animated “superlikes” to other stories. Create audience lists beyond “best friends.” Why it is important. Instagram openly recognizing that gossip and obsession with the metrics of your stories are behaviors widespread enough to monetize. But there is something that is also very important: being able to highlight stories so that they are seen more is a change in the rules of the game. These types of functions end up creating a distinction between users that affects not only the functionalities to which they have access, but also the visibility of their content. Why now. This is the next question to ask ourselves. Instagram is, along with Facebook, the social network that generates the most incomeso it’s not that you have a liquidity problem. However, right now Meta’s actions are not going through their best momentlargely due to the mistrust generated by the astronomical spending on infrastructure for AI. With 3 billion active usersInstagram Plus has the potential to boost revenue even more to face what is coming. TObackground. Instagram is following in the footsteps of other social networks that have opted for this type of subscriptions. We saw the case of the most aggressive subscription model with Twitter (now X), which after the acquisition by Elon Musk completely changed the meaning of the blue tick. Today, if you don’t pay you can’t send messages to any user, edit posts, create longer posts or access Grok. At the other extreme we have Snapchat+, which is a subscription that adds benefits without deteriorating the free experience. Among its features are being able to access experimental features first, more storage, and access to premium lenses. They launched it in 2022 and they have done quite well: Today it has 25 million subscribers and has generated 1 billion in revenue. Availability and price. At the moment, Instagram Plus is going to be tested in a limited number of countries. Meta hasn’t said which ones, but we know it has already appeared in Japan, the Philippines and Mexico. Regarding prices, according to some users have postedin Mexico it is 39 pesos per month, which at the current exchange rate is 1.88 euros. It is not clear in which other countries they will test it or when they plan to launch it globally. Image | Sanket Mishra, Pexels

from sharing mobile data to paying again like a decade ago

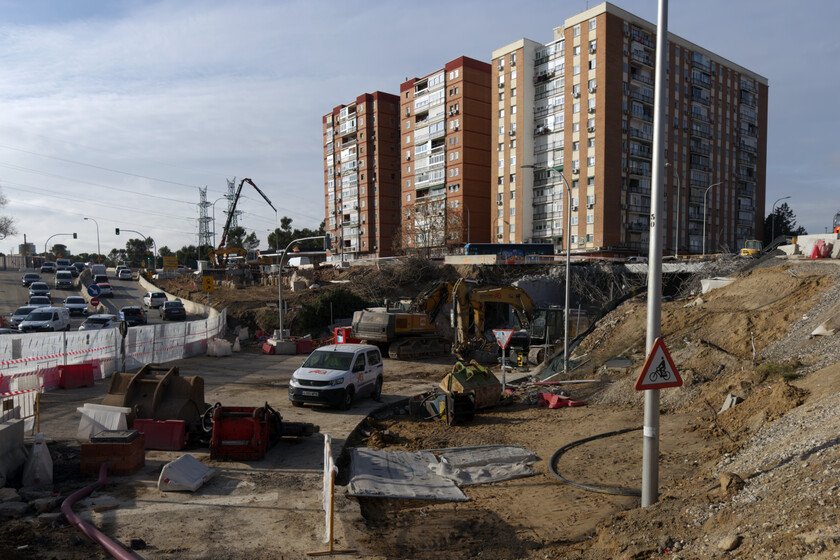
Saturday is a good day to have your internet cut off. At first you don’t notice, because you’re at home and you don’t use the computer (as much). But you end up finding out, and that’s what happened to me when I realized that I was without my O2 fiber connection, againfor the underground works from the A-5, again. Two days later I’m still the same, like many residents of the area, and this is becoming a small (but bearable) headache. The cuts are back. These works have already caused cuts in the past. They did it in July, August and November of 2025, and also in January 2026. Each time the affected areas and operators have occurred, they have varied, but for example on social networks there is data that indicate that this time the cut has been important and has affected to Movistar/O2 clients,Orange, VodafoneJazztel or Digi. Meanwhile, unlimited data. Spotting the problem on Saturday morning, I called my operator, O2, to find out what was happening. They confirmed to me that it was a fiber optic cable cut due to the works on the A-5, and they explained to me that they hoped to resolve the problem as soon as possible. And as in the previous outage, they told me that during this period I was offered unlimited mobile data on all the lines associated with my contract. It is something that operators usually offer in these cases and that certainly makes the problem mitigate… although it does not disappear. He tethering saves (quite a lot) the papers. Since then I have been using my computer with mobile data: I have shared the connection on my smartphone through tetheringwhich allows me to work normally and at decent speeds without problems. This weekend I have also used this connection, sharing it with the Chromecast on my TV to watch a series or movie without problems. Paying as before. Businesses in the area have also been affected by these service cuts, and the example is a supermarket near my house where this weekend there was no option to pay with a mobile phone. The POS did not accept contactless payments and you had to pay either in cash or with a physical debit/credit card, inserting it into the POS slot. Better to be proactive. Users have few options here beyond calling the operator to find out what happened and to have them activate that unlimited data if they had not already done so. Here it is advisable to be proactive and call because at least in my case until I called they did not activate those unlimited “bonuses”, and it makes sense: the operators may not know which users exactly are affected. If we want to have this option we will have to call and probably wait a few minutes until an agent answers us, something that may take time because these breakdowns affect many people. In my personal case the wait was about 5 or 6 minutes this time. It’s time to wait. As is often the case on these occasions, there is no clear estimate of when the problem can be resolved. In January the disconnection lasted approximately two days, and this time the outage is already on its way to lasting up to three days or more. Neither the operators nor the Community of Madrid offer much information in this regard, and in most cases the only thing that users can do is be patient. In Xataka | There is an extensive system to avoid being cut off in the 48 km underground of the M-30. It’s time to renew it

Paying more for a very fast NVMe SSD is wasting money if you only save PDFs, but it is the only option if you are also going to work from it

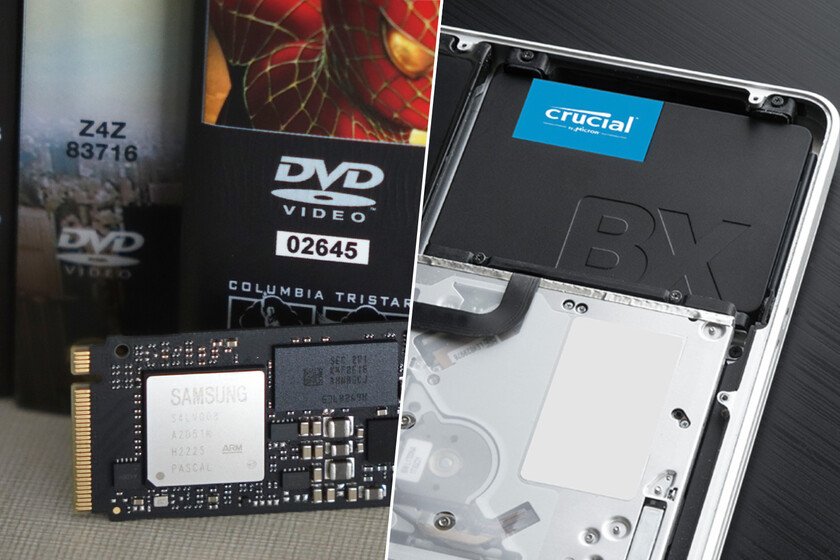
Like me, you have probably also at some point faced the purchase of a new storage unit, internal or external, for your desktop PC or portable. Something that, until a few years ago, was quite simplified: either you chose a 5,400 rpm HDD (revolutions per minute), or you chose one of 7,200 rpm. End of story. To something else. But since SSDs came onto the scene, purchasing (and usage) possibilities have changed a lot, making opting for one type or another is not so simple. Today, taking into account the price differences between HDDs (the “old” mechanical disks) and SSDs (the “modern” solid state drives), the choice is clear: SSDs win by a landslide, offering wide capacities and much, much higher speeds. Although well, the current context of AI surcharges It changes the film a little and, whatever purchase we make now, it will entail a greater outlay. But this shouldn’t last forever and, under normal conditions, SSDs are still the best value for money purchase option for general use. The price could vary. We earn commission from these links So, well, you already have one thing clear: to expand capacity, in general terms, the ideal in 2026 is to go for an SSD. However, the choice is not so simple because different technologies and different models come into the field of SSDs, each with a series of advantages and disadvantages. All of them, valid for any use you plan to give them, be careful. But not all of them cost the same and, depending on what you need your new unit for, Smart purchasing will tip the balance on one side or the other. And your pocket, of course, will thank you for choosing carefully. In other words and to give them first and last names: in a scenario in which you need more space for your PC or portable and you have to go through the checkout to expand it using an SSD, you will have to choose between an NVMe SSD or a SATA SSD (which are the main types of SSD that are generally sold). The first, more expensive and faster. The second, cheaper and slower. AND each one, in its proper context, shines with its own light. Next we are going to see how they differ and why they are a better purchase option compared to their rival, depending on the context. And thus pay more if the situation requires it or save as much as possible if you are not going to take advantage of its full potential. SATA SSD: not as fast but cheaper When SSDs burst onto the scene, they did so in a format we know as SATA. In units of different sizes (although also ostensibly more compact than mechanical HDDs) that are still commonly marketed in 2.5-inch models. If you have a laptop or desktop PC from a couple of decades ago, probably contains one of these. These SSD units were, at the time, night and day compared to mechanical HDDs. What used to take you half an hour to wait was suddenly completed in minutes. And also, without noise. The “problem” is that today, with much more modern and faster units (spoiler: NVMe), this type of SSD have been relegated more to pure storage than as devices for daily work. That is to say: what we once stored on HDDs, we now do on these SSDs. A digital storage room that, in any case, is much faster and makes it easier (and faster) to move large amounts of data and copy and paste files. In addition, the SATA SSD is probably the only option when it comes to somewhat “old” laptops: today, practically all models come with an M.2 connector (where the NVMe are installed), but if you have a laptop that is a few years old (around 2018 or earlier) it will probably not have said connector and the 2.5-inch SATA SSD is the one you will have to use. If you are also using a mechanical HDD, the change will be spectacular. Does this mean they are a bad choice? Not at all, they’re still great in 2026… but especially for what I’m doing: storing. Because if what you need is a “hard drive” on which to install the operating system, applications and games, or on which work intensively on tasks that require constant writing and reading of data (such as video editing), then you will be limited. This leads us to the next model: NVMe SSD. NVMe SSDs: faster and more expensive While SATA SSDs are somewhat larger and slower (but cheaper), NVMe SSDs are a rocket. The quickest and most direct way to describe them is: speed, speed, speed. While the former would become a one-lane national highway, the latter become a highway with eight lanes in each direction. This means that if a sporadic car (some file, such as PDFs) is going to pass through these “roads”, SATA is enough for you; If you need several heavy trucks moving at the same time (video editing, for example, with thousands of MB of data moving at full speed) then That national highway will collapse and there is no choice but to drive on the highway.. NVMe SSDs also stand out in design: they are compact, stylish and very small. The inseparable companion of any current desktop or laptop PCbut also in video game consoles by offering better performance in all types of tasks and taking up less space (something vital, for example, in the case of consoles). In fact, this is the type of SSD that the PlayStation 5, the Steam Deck… come with in the M.2 connectors that they incorporate. Connector that, by the way, has been present on practically any desktop or laptop motherboard for a few years now. This type of SSD is more expensive than its SATA relatives, but that extra financial effort is worth it if, in addition to storing data as such, you plan to work on them. … Read more

Google has made AI consume up to six times less memory. Micron, Samsung and SK Hynix are paying dearly

we carry months wrapped in the memory crisisbut maybe there is a way out. Last week Google Research published a study in which he revealed a technique called TurboQuant. This is a compression algorithm capable of compressing the working memory of AI models up to six times without appreciable loss of quality or performance. Great news for end users, who see a light at the end of the tunnel, but terrible news for manufacturers, who this golden age could end. Let’s explain what KV cache is.. To understand TurboQuant you have to understand what that memory is that it manages to compress. When a language model processes a long conversationyou need to remember the context. Each token that is processed is stored in the so-called KV cache, a type of working memory that grows as we chat. The longer the conversation, the more memory the model requires. Compressing what is a gerund. It is one of the main bottlenecks in the AI ​​inference stage (that is, when we use the models), and one of the reasons why data centers they need as much RAM or HBM memory. TurboQuant uses a vector quantization method to compress this cache while maintaining the precision of the model. Pied Piper. As soon as this Google study appeared, the analogies began with the plot of the series ‘Silicon Valley’. In it, the fictional startup in the plot managed to develop an extraordinarily efficient compression algorithm called Pied Piper that threatened to revolutionize the technology industry. These days, multiple references to the series appeared on social media, which had already been referred to as visionary for reflecting what is happening with spectacular accuracy even when the series was a comedy. Six times less memory. The Google Research paper states that this method is capable of reducing the KV cache six times without an appreciable difference in performance in long conversations. The researchers will present their results at an event next month and explain the two methods that allow it to be put into practice. If they confirm what they’ve already teased, the implications are huge: less memory for inference means data centers can do the same thing with much less hardware/memory. Google’s DeepSeek moment. The discovery has some analysts calling this Google’s “DeepSeek moment.” A year ago, the Chinese startup DeepSeek launched an AI model that competed with the best but had cost much less to develop. That shook the industry, and now we return to a technical achievement that points to the same thing. In AI, doing the same with less is crucial, given the enormous resources that this technology requires. There are those who already have done evidence preliminaries with TurboQuant and have confirmed that the method does indeed work. Micron, Samsung and SK Hynix pay dearly. The impact of this technique can be enormous, and this has already begun to be noticed in the stock market valuations of DRAM memory manufacturers and HBM. Companies like Micron, Samsung, SK Hynix, SanDisk and Kioxia fell noticeably last week from their recent highs. On March 18 it was around $471, and today its shares are at $357, a staggering 24.2% drop. The same has happened with the rest of the manufacturers, which were already falling since that date, but have accelerated that fall with the launch of TurboQuant. But. The technique can theoretically be applied only to the inference phase, but the training phase of AI models is not affected by this compression technique. Therefore, huge amounts of memory will still be needed during the training phase. Besides we will have to wait for AI companies to actually start applying said system if it is confirmed to work, and that will be when we can see the real impact. Theoretically this will give a lot of room for maneuver to big tech, which will be able to reduce token prices even further, but it remains to be seen if they do so. RAM memories drop in price. The impact of TurboQuant has also been clear in the prices of memory modules, which have dropped appreciably in price. For example, the Corsair Vengeance DDR5 32 GB 6000MHz (2x16GB) modules were at 489.59 euros on Amazon until a few weeks ago according to CamelCamelCamel, but right now they are at 339.89 euros, a notable discount. It is true that not all components are falling equally, but there are indeed cases in which reductions seem to be occurring. In Xataka | The RAM crisis is destroying all of Valve’s plans with its Steam Machine

Is it worth paying twice as much for a mobile phone that has changed so little?

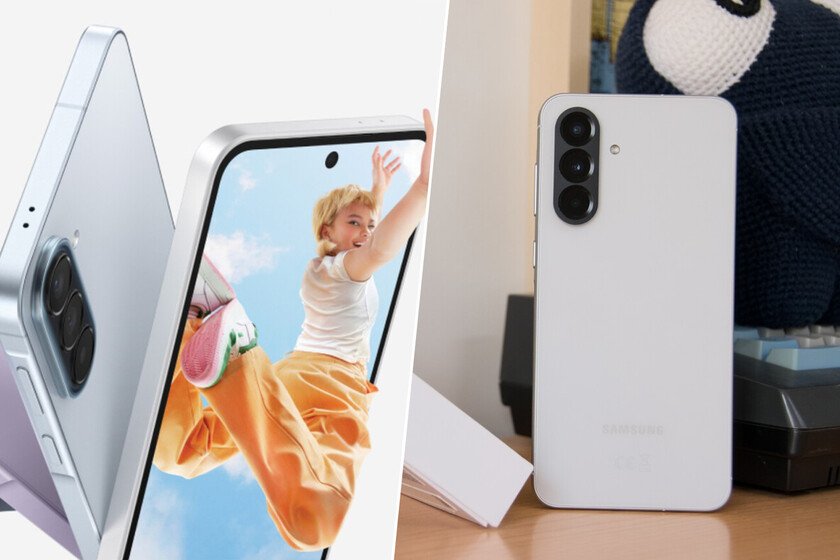
Samsung has been faithful to its annual event and presented a few hours ago the new Galaxy A57 (next to Galaxy A37). This is placed as the best mid-range phone that South Koreans havealthough you may very well be wondering how it is different from Galaxy A56last year’s model. To make it very easy for you, we are going to see the main differences so that you have it easier when choosing one or the other right now. The price could vary. We earn commission from these links Samsung Galaxy A56 5G, Android smartphone, 256 GB storage, 8 GB RAM, anthracite, 6X update, large screen, long life (warranty) The price could vary. We earn commission from these links The differences between the Galaxy A57 and the Galaxy A56 Continuous design, but lighter and thinner At first glance, both Samsung devices are quite similar. Both the Galaxy A56 and the Galaxy A57 rely on a metal edge and a glass back where the camera module sticks outso both one and the other will “limp” you if you place them with the screen facing up on a table. Now, there are changes in dimensions and weight. Samsung has been insisting on making its phones thinner for some time (the Galaxy S26 family is the perfect proof of this) and the Galaxy A57 is no exception. We are faced with a mobile that It is only 6.9 millimeters thicka good cut if we take into account that the A56 is 7.4 millimeters. There is also a notable difference in weight: the new model weighs 179 grams compared to the 198 grams of its predecessor. All this translates into a better in-hand experience. Processor and memory configurations Samsung continues to rely on its own Exynos processors for its mid-range phones. The new Galaxy A57 mounts the Exynos 1680a direct evolution of the Exynos 1580 that its predecessor rides. We do not have data yet on the performance of this new CPU, but hopefully it will be more powerful and efficient. The Galaxy A56, as we told you in its analysis, offers plenty of power for everyday life and the most common apps, something that will not change with the new model. There are also differences at the memory level. The Galaxy A56 started with 6 GB of RAM, although it had an 8 GB configuration. The new model raises the level and starts with 8 GB of RAMalthough with the possibility of purchasing a version with 12 GB of RAM. It also goes up a level in storage, now starting from 256 GB with the possibility of choosing 512 GB, something that the Galaxy A56 did not offer (which started from 128 GB and went up to 256 GB). Lots of AI and six years of updates As usual, the new Galaxy A They come hand in hand with a more modern version of One UI, Samsung’s custom layer based on Android. In this case it is One UI 8.5 (Android 16), although the most interesting thing is once again the years of support that the company offers for these phones. The Galaxy A57 has six years of guaranteed updatesso you will receive up to Android 22. Logically, coming out in 2025, the Galaxy A56 will receive one year less of updates at this point. AI is one of the key pieces of Samsung software, also in the Galaxy A57. Beyond Galaxy AIwe can expect this device to come with features like voice transcription on the recorder, smart object erase or ‘Circle to Find’, as well as Gemini. However, all of these functions They should also be present on the Galaxy A56. Few changes at the battery and camera level We are mainly emphasizing the differences between both terminals, but it is also important to point out where there are no changes. The battery is one of these aspects, since both devices have a 5,000 mAh battery. Although it is true that this figure is far from silicon-carbon batteries that other manufacturers mount, Samsung devices are very well optimized. Both one and the other should give you more than a day of autonomy. In addition to fast charging (which in both cases is 45 W via cable), they also repeat the same cameras, both rear and selfie camera. There may be differences when testing them thanks to the processing and artificial intelligence, although we still have to wait to issue a verdict here. The price has a lot to say right now Of course, if we talk about differences, we must put the price into the equation. The new Galaxy A57, which comes out on April 10, starts at 529 euros in its configuration with 128 GB of storage and 8 GB of RAM. On the other hand, the Galaxy A56 right now can be found much cheaper. In fact, the version with 256 GB of storage and 8 GB of RAM comes out 284.12 euros (with the discount coupon ‘ASES43’). In summary: which Galaxy to choose based on your needs Why choose the Galaxy A57 Although there are not many changes, there are. The problem is that may not be enough to justify paying the price difference what’s there right now. This is where the new model stands out the most: It comes with a new processor: We don’t have figures yet, but the new Exynos chip, on paper, is more powerful and efficient. It is lighter and thinner– The Galaxy A57 has become lighter and thinner. With an almost identical design, this new mobile is more comfortable in hand. Initial storage configuration is better: Starting from 8 GB of RAM and 256 GB of storage, the cheapest version is better than the Galaxy A56. You are looking for the greatest possible longevity: Both devices have six years of updates, but this one has arrived a year later, so it will receive more updates (both operating system and security). The price could vary. We earn commission from these links Why choose the … Read more

Log In

Forgot password?

Forgot password?

Enter your account data and we will send you a link to reset your password.

Your password reset link appears to be invalid or expired.

Log in

Privacy Policy

Add to Collection

No Collections

Here you'll find all collections you've created before.